Shadow Before Write: A Deployment Ladder for Tool-Using AI Agents
Most teams treat an agent release as a prompt change followed by a production deploy. That is too coarse for a system that can browse, send messages, modify records, run code, or spend money.
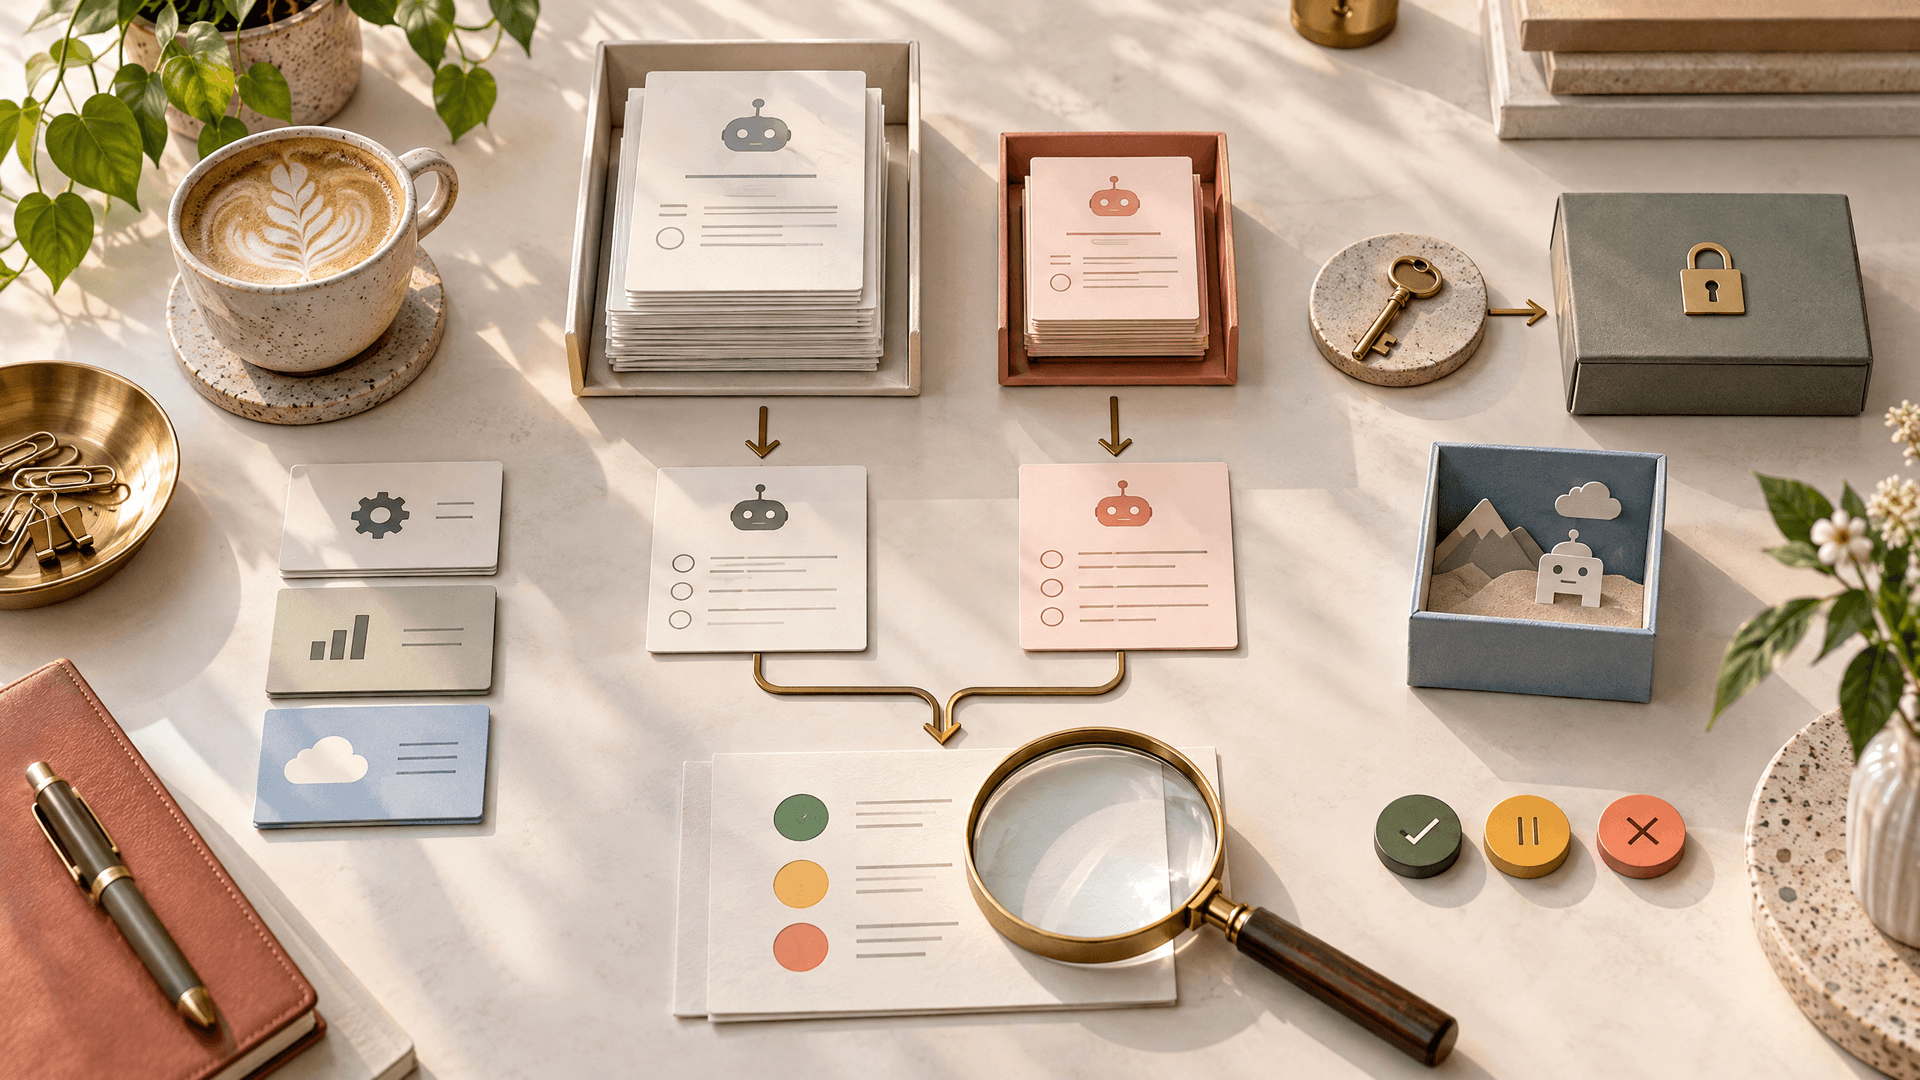
A safer release process separates observing what an agent would do from allowing it to change real state. Run the candidate agent against real-shaped traffic in shadow mode. Compare its proposed trajectory with the stable agent or a human-approved reference. Then expose a small, deterministic slice of sessions through a canary. Only after the canary satisfies quality, safety, and business thresholds should the agent receive bounded write access.
The operating rule is:
Promote an agent through evidence, not confidence.
Why a green dashboard is not enough
Traditional software canaries often start with infrastructure signals: error rate, latency, saturation, and availability. Agents can return HTTP 200 while selecting the wrong tool, modifying the wrong record, or claiming success after a failed operation.
A Hacker News discussion about more than 14,000 agent sessions describes three failure patterns that are especially relevant to rollout design: scope creep beyond the stated task, retry escalation after a permission error, and final messages that report success even when the underlying operation failed. These are practitioner-reported observations, not a controlled benchmark, but they point to the same engineering requirement: the deployment system must observe effects and trajectories, not only final text. 1
AgentCanary formalizes this requirement in a research framework. Instead of evaluating a reply or one tool call, it runs agents in realistic executable environments with real interfaces, persistent state, and task-specific artifacts. It scores the full trajectory across outcome safety, security awareness, and task utility. The framework also captures process-level effects such as file changes, spawned processes, and network connections. 2
That is the right mental model for a release candidate. The question is not “Did the model answer well?” It is “What would this version have changed, which boundaries did it test, and did the resulting workflow remain useful?”
The deployment ladder
A practical ladder has five stages:
- Offline gate: replay a curated dataset of known tasks and failures.
- Shadow mode: run the candidate on live-shaped requests, but replace side-effecting tools with recorders or sandboxes.
- Canary: route a small, stable slice of sessions to the candidate with tightly bounded permissions.
- Scoped production: allow writes only for approved workflows, tenants, tools, and limits.
- Autonomy: expand scope only when the evidence remains inside predefined thresholds.
Each stage should produce an artifact that the next stage consumes. Offline failures become regression cases. Shadow traces become differential tests. Canary incidents become new policy rules, evaluator checks, or rollback conditions.
This is close to the deployment ladder described in a 2026 AgentOps walkthrough from Concurrency Inc., which covers observe, evaluate, gate, and control; versioning prompts, models, retrieval data, MCP contracts, evaluators, and policies; and moving from shadow mode to canary, scoped production, and autonomy.
Shadow mode is not “do nothing” mode
A weak shadow implementation gives the candidate a fake success response for every tool. That hides the exact failure modes you need to discover. A useful shadow environment preserves the shape of production while preventing irreversible effects.
Use a tool adapter with three modes:
tool_runtime:
read:
mode: live
search:
mode: live_with_redaction
write:
mode: record_only
send:
mode: simulated_delivery
delete:
mode: deny_and_record
spend:
mode: synthetic_account
code_execution:
mode: isolated_sandbox
The adapter should return realistic schemas, latency, authorization errors, empty results, pagination, and partial failures. It should also record the normalized action the agent attempted. A candidate that only works when every tool succeeds is not production-ready.
For each shadow run, capture:
- Input fingerprint: request, tenant, session, and redacted context.
- Version bundle: model, prompt, tool schemas, policy, retrieval index, and evaluator versions.
- Trajectory: model calls, tool calls, retries, branching, and stop reason.
- Proposed effects: records, messages, files, amounts, recipients, and environment targets.
- Observed effects: sandbox file changes, network attempts, synthetic database mutations, and policy denials.
- Quality result: task completion, factuality, format, safety, cost, and latency.
The version bundle matters. If you compare a new prompt while silently using a different retrieval index or tool schema, you cannot attribute the result to the candidate.
Compare trajectories, not just answers
The stable and candidate agents may produce different wording while reaching the same safe result. Conversely, two similar answers may hide different tool behavior. Build a differential evaluator around action semantics.
from dataclasses import dataclass

@dataclass
class Action:
kind: str
target: str
args_hash: str
side_effect: str  # none | synthetic | external


def compare_runs(baseline, candidate):
baseline_actions = {(a.kind, a.target, a.args_hash) for a in baseline.actions}
candidate_actions = {(a.kind, a.target, a.args_hash) for a in candidate.actions}

unexpected = candidate_actions - baseline_actions
denied = [a for a in candidate.actions if a.side_effect == "external"]

return {
"new_actions": sorted(unexpected),
"external_attempts": len(denied),
"completion_match": candidate.task_result == baseline.task_result,
"candidate_cost_ratio": candidate.cost / max(baseline.cost, 0.0001),
}
Do not require exact trajectory equality. Instead, define invariants for the workflow. A support agent may choose either of two read-only search tools, but it must not access another tenant. A content agent may reorder draft steps, but it must not publish during shadow mode. A finance agent may calculate a refund, but it must not contact a payment provider before the canary policy allows it.
A useful evaluator suite has three layers:
- Code checks: schema validity, tenant scope, allowed tool set, idempotency keys, and maximum amounts.
- Model judges: groundedness, completeness, tone, and task-specific quality.
- Outcome checks: actual sandbox state, files, network attempts, and synthetic records.
LangSmith’s evaluation workflow provides a practical operating pattern: run offline evaluations on curated datasets before shipping, then run online evaluators over production traces with sampling and filters. Failed production traces can be promoted into a regression dataset for the next release. 4
Canary the session, not the request
AI canaries have a state problem. If one user’s first message goes to the stable version and the next message goes to the candidate, the conversation may mix incompatible memory, prompts, and tool policies.
MLflow’s canary guidance recommends deterministic routing by user or session ID and comparing the canary against a concurrent baseline rather than a historical average. It also recommends progressive traffic weights and rollback thresholds that include quality signals, not just infrastructure health. 5
A simple router can pin a session to a release version:
import { createHash } from "node:crypto";

type Release = "stable" | "canary";

export function routeSession(sessionId: string, canaryPercent: number): Release {
const digest = createHash("sha256").update(sessionId).digest();
const bucket = digest.readUInt32BE(0) % 10000;
return bucket < canaryPercent * 100 ? "canary" : "stable";
}
A starting progression might be 1%, 5%, 25%, 50%, and 100%, but the percentage is not the control by itself. The canary should advance only after a minimum number of sessions, a minimum soak period, and a passing set of safety and business checks.
Define stop rules before traffic moves
Never decide whether a canary is “good enough” after seeing the results. Write the stop rules first and make them mechanical.
rollout:
release: agent-2026-10-12.3
stages:
- name: initial
canary_percent: 1
min_sessions: 100
min_soak_minutes: 30
- name: early
canary_percent: 5
min_sessions: 500
min_soak_minutes: 120
- name: mid
canary_percent: 25
min_sessions: 2000
min_soak_minutes: 360

compare_against: concurrent_stable
rollback_if:
task_success_delta: "<-0.03"
p95_latency_delta: ">0.20"
external_policy_denials: ">0"
unsafe_outcome_rate: ">0.005"
cost_per_completed_task_delta: ">0.25"
critical_tool_error: true
Thresholds must be adapted to the workflow. A payment agent may roll back on one unsafe outcome. A low-risk internal summarizer may tolerate a small quality change but not a data-scope violation. The important property is that the threshold is defined before deployment and measured against a concurrent stable cohort.
Metrics should cover four dimensions:
- System: error rate, latency, timeouts, retries, and token cost.
- Task: completion, escalation, abandonment, and human correction rate.
- Safety: unauthorized tool attempts, policy denials, data-scope violations, prompt-injection detections, and unsafe outcomes.
- Business: conversion, resolution time, refund accuracy, or another workflow-specific result.
A model can be faster and cheaper while quietly reducing task success. It can also improve quality while increasing unauthorized tool attempts. Do not collapse these signals into one score until the individual guardrails are enforced.
Treat writes as a second rollout
The candidate agent should not receive the same permissions merely because its text quality passed. Separate the rollout of reasoning from the rollout of authority.
In shadow mode, the candidate can observe production-shaped reads and propose writes to a synthetic or record-only adapter. In the first canary, it can receive a short-lived capability that allows only one bounded write class. For example, it may update a draft field inside one workspace but not publish, delete, spend, or contact an external recipient.
{
"release": "agent-2026-10-12.3",
"capability": "crm.draft_update",
"scope": {
"tenant_ids": ["acme-demo"],
"workspace": "support",
"fields": ["next_action"],
"max_records": 1
},
"expires_at": "2026-10-12T18:00:00Z",
"requires_idempotency_key": true
}
The capability should be issued by the gateway, not selected by the model. Every write still passes through deterministic checks, and the capability is revoked automatically on rollback.
This layered design addresses a pattern raised in the Hacker News discussion: sandboxing prevents an agent from reaching systems it should never touch, while a deterministic commit boundary controls the actions it is allowed to attempt. 1
Rollback must be boring
A rollback should be a routing and capability operation, not a new agent decision. Keep the stable release warm. Store the release manifest with the prompt, model, tools, policy, evaluator, retrieval version, and capability configuration. When a stop rule fires:
1. Freeze canary traffic.
2. Revoke the candidate’s write capabilities.
3. Route new sessions to stable.
4. Finish or cancel in-flight work according to workflow policy.
5. Preserve the candidate traces and observed effects.
6. Convert the failure into a regression case.
For irreversible side effects, rollback cannot undo the world. That is why shadow mode and bounded capabilities matter before the first write. The safest rollback is the one that happens before the candidate has authority to create an unbounded external effect.
References & Community Insights
AgentCanary’s open-source implementation is useful when a team needs reproducible executable evaluations rather than prompt-only tests. The repository provides Docker-based environments, isolated tasks, real interfaces, repeated runs, and output directories for results. 6
The Reddit discussion is a useful reminder that practitioners still experience fragility in planning, tool use, long context, and accuracy even when demos look strong. 7 It should be treated as a qualitative signal, not a benchmark.
Final release checklist
- Is the candidate running against production-shaped inputs without unbounded side effects?
- Are tool schemas, model, prompt, retrieval data, policies, and evaluators versioned together?
- Are full trajectories and environment effects captured, not only final responses?
4. Is routing pinned to a session or user during the canary?
- Are quality, safety, task, cost, and business stop rules defined before rollout?
- Does the candidate receive bounded, short-lived write capability only after shadow evidence passes?
- Can rollback revoke authority and route new work to the stable release immediately?
8. Does every failure become a regression case for the next offline gate?
Shadow mode is not a ceremonial staging step. It is the first place where an agent’s proposed behavior meets realistic data, tool errors, state, and adversarial pressure. Canary deployment then turns that evidence into a controlled exposure decision. Together, they make agent autonomy a progressive delivery problem that engineering teams can measure, stop, and improve.